More about forecasting in cienciadedatos.net
- ARIMA and SARIMAX models with python
- Time series forecasting with machine learning
- Forecasting time series with gradient boosting: XGBoost, LightGBM and CatBoost
- Forecasting time series with XGBoost
- Global Forecasting Models: Multi-series forecasting
- Global Forecasting Models: Comparative Analysis of Single and Multi-Series Forecasting Modeling
- Probabilistic forecasting
- Forecasting with deep learning
- Forecasting energy demand with machine learning
- Forecasting web traffic with machine learning
- Intermittent demand forecasting
- Modelling time series trend with tree-based models
- Bitcoin price prediction with Python
- Stacking ensemble of machine learning models to improve forecasting
- Interpretable forecasting models
- Mitigating the Impact of Covid on forecasting Models
- Forecasting time series with missing values
Introduction
When trying to predict future values, most forecasting models try to predict the most likely value. This is called point-forecasting. Although knowing the expected value of a time series in advance is useful in almost any business case, this type of prediction does not provide any information about the confidence of the model or the uncertainty of the prediction.
Probabilistic forecasting, as opposed to point-forecasting, is a family of techniques that allow the prediction of the expected distribution of the outcome rather than a single future value. This type of forecasting provides much richer information because it allows the creation of prediction intervals, the range of likely values where the true value may fall. More formally, a prediction interval defines the interval within which the true value of the response variable is expected to be found with a given probability.
Skforecast implements several methods for probabilistic forecasting:
- Bootstrapped residuals: Bootstrapping is a statistical technique that allows for estimating the distribution of a statistic by resampling the data with replacement. In the context of forecasting, bootstrapping the residuals of a model allows for estimating the distribution of the errors, which can be used to create prediction intervals.
Conformal prediction: Conformal prediction is a framework for constructing prediction intervals that are guaranteed to contain the true value with a specified probability (coverage probability), under the assumption that the data are exchangeable. In time series this assumption holds only approximately, so the empirical coverage should always be validated. It works by combining the predictions of a point-forecasting model with its past residuals (differences between previous predictions and actual values). These residuals help estimate the uncertainty in the forecast and determine the width of the prediction interval that is then added to the point forecast. Skforecast implements Split Conformal Prediction (SCP).
Conformal methods can also calibrate prediction intervals generated by other techniques, such as quantile regression or bootstrapped residuals. In this case, the conformal method adjusts the prediction intervals to ensure that they remain valid with respect to the coverage probability.
- Quantile regression: Quantile regression is a technique for estimating the conditional quantiles of a response variable. By combining the predictions of two quantile regressors, an interval can be constructed, with each model estimating one of the bounds of the interval. For example, models trained on $Q = 0.1$ and $Q = 0.9$ produce an 80% prediction interval ($90\% - 10\% = 80\%$).
⚠️ Warning
As Rob J Hyndman explains in his blog, in real-world problems, almost all prediction intervals are too narrow. For example, nominal 95% intervals may only provide coverage between 71% and 87%. This is a well-known phenomenon and arises because they do not account for all sources of uncertainty. With forecasting models, there are at least four sources of uncertainty: the random error term, the parameter estimates, the choice of model for the historical data, and the continuation of the historical data generating process into the future. When producing prediction intervals for time series models, generally only the first of these sources is taken into account. Therefore, it is advisable to use test data to validate the empirical coverage of the interval and not only rely on the expected one.
💡 Tip
This is the first in a series of documents on probabilistic forecasting.
Metrics in probabilistic forecasting
In point forecasting, the model outputs a single value for each future step, and the quality of the predictions is assessed by comparing the predicted value with the true value of the series. Examples of metrics used for this purpose are the Mean Absolute Error (MAE) and the Root Mean Squared Error (RMSE).
In probabilistic forecasting, the model does not produce a single value, but a representation of the distribution of possible values. In practice, this is a sample of the distribution (for example, 150 bootstrapped predictions) or a set of quantiles from which prediction intervals are built. The quality of such predictions cannot be assessed with point metrics. Two properties have to be evaluated:
Calibration: the intervals contain the true value as often as their nominal level promises. An 80% interval should contain around 80% of the observed values.
Sharpness: how narrow the intervals are. For a given coverage, narrower intervals are more informative.
There is a trade-off between both properties: an extremely wide interval always achieves the nominal coverage, but it is useless. The goal is to produce intervals that are as narrow as possible while still capturing the true values with the desired probability.
| Metric | Aspect evaluated | Description |
|---|---|---|
Coverage: calculate_coverage |
Calibration | Proportion of true values that fall within the prediction interval. It should be close to the nominal level. |
| Interval area | Sharpness | Sum of the widths of the intervals (upper bound minus lower bound) over all the predicted steps. For a given coverage, the smaller the better. |
Winkler score (interval score): winkler_score |
Calibration and sharpness | Width of the interval plus a penalty, proportional to $2/\alpha$, for each observation that falls outside the interval, where $1 - \alpha$ is the nominal coverage. The lower the better. |
Weighted Interval Score (WIS): weighted_interval_score |
Calibration and sharpness | Generalizes the Winkler score to several intervals plus the median forecast. It is a discrete approximation of the CRPS. |
CRPS: crps_from_predictions, crps_from_quantiles |
Full distribution | Distance between the predicted and the empirical cumulative distribution functions. It evaluates the entire predictive distribution. |
The Winkler score, the WIS and the CRPS are proper scoring rules that combine calibration and sharpness into a single number, which makes them convenient for comparing methods. In this document, the intervals are evaluated with the empirical coverage, the area and the Winkler score.
Bootstrapped Residuals
Forecasting intervals with bootstrapped residuals is a method used to estimate the uncertainty in predictions by resampling past prediction errors (residuals). The goal is to generate prediction intervals that capture the variability in the forecast, giving a range of possible future values instead of just a single point estimate.
The error of a one-step-ahead forecast is defined as the difference between the actual value and the predicted value ($e_t = y_t - \hat{y}_{t|t-1}$). By assuming that future errors will be similar to past errors, it is possible to simulate different predictions by taking samples from the collection of errors previously seen in the past (i.e., the residuals) and adding them to the predictions.
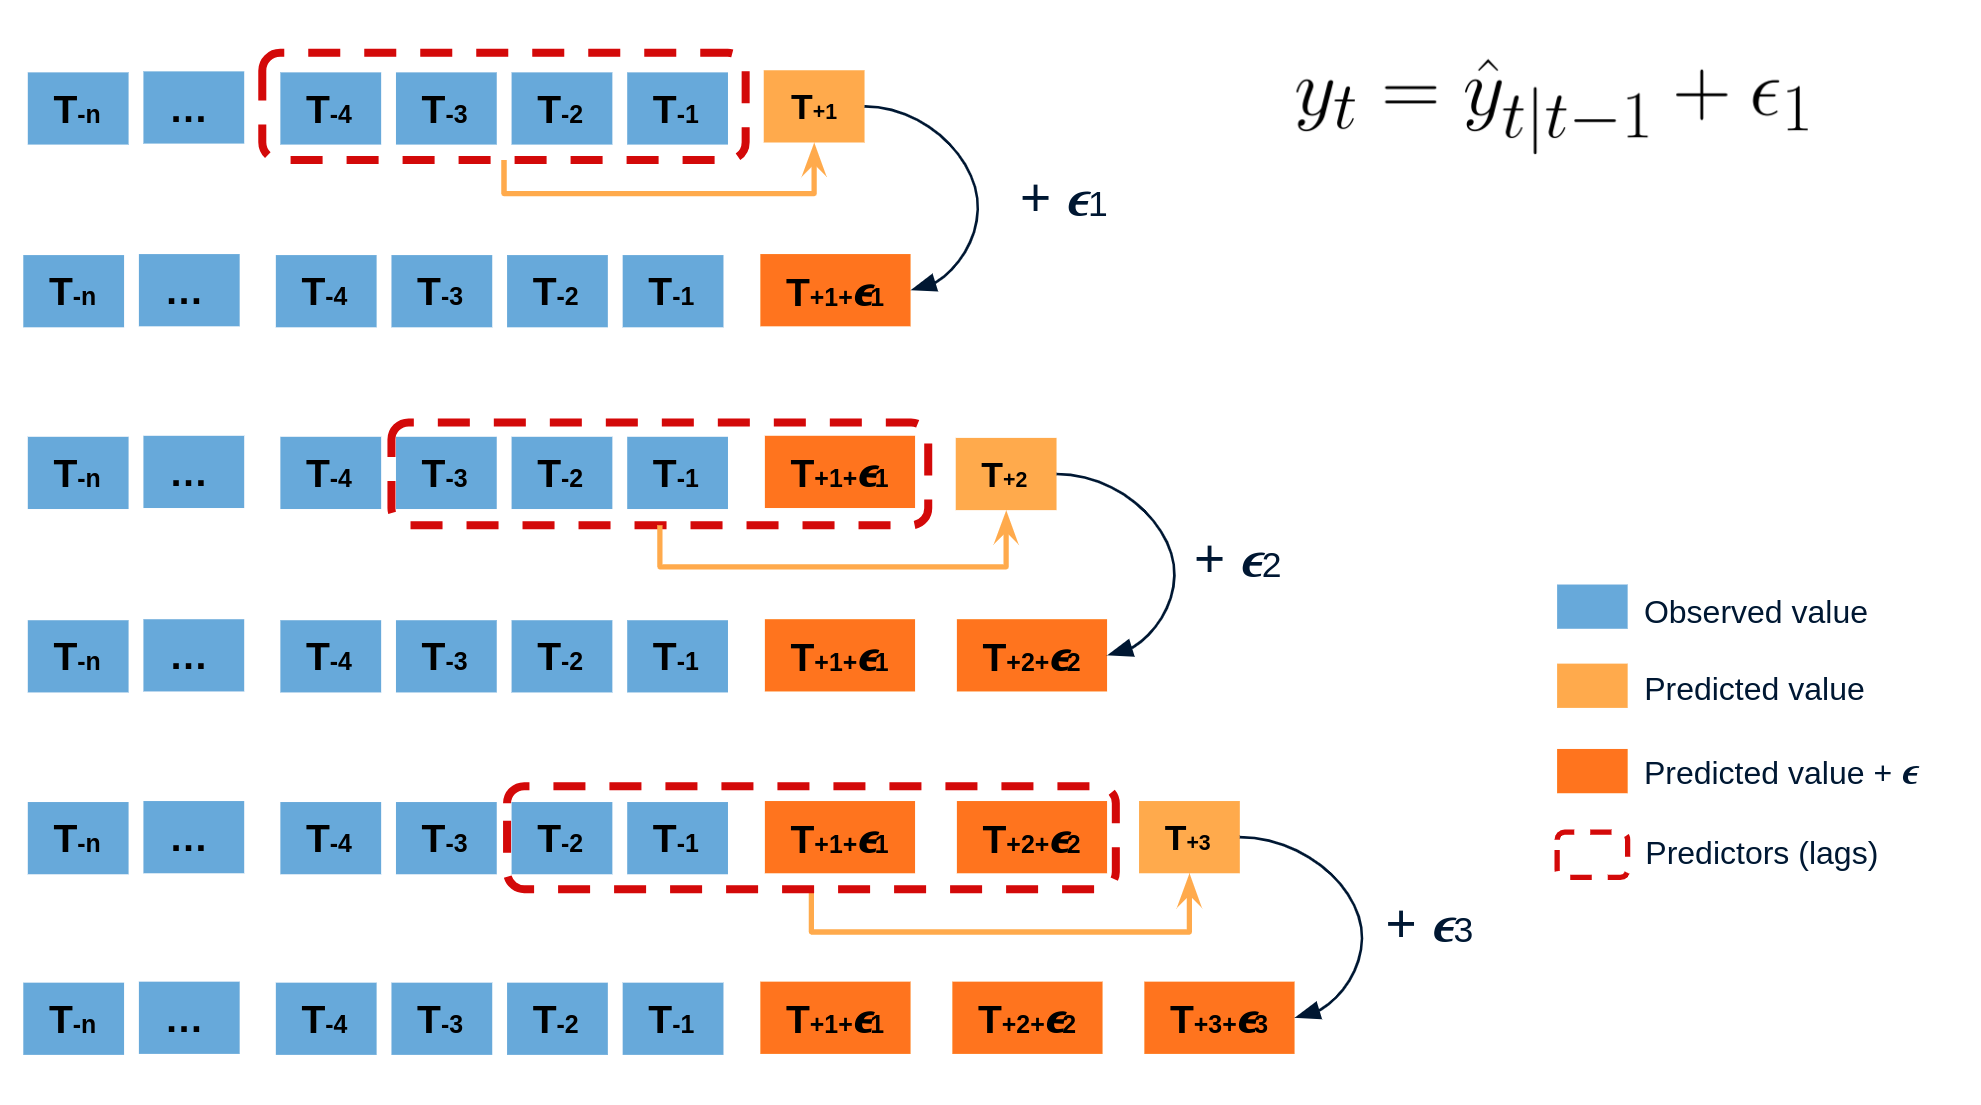
Diagram bootstrapping prediction process.
Repeatedly performing this process creates a collection of slightly different predictions, which represent the distribution of possible outcomes due to the expected variance in the forecasting process.
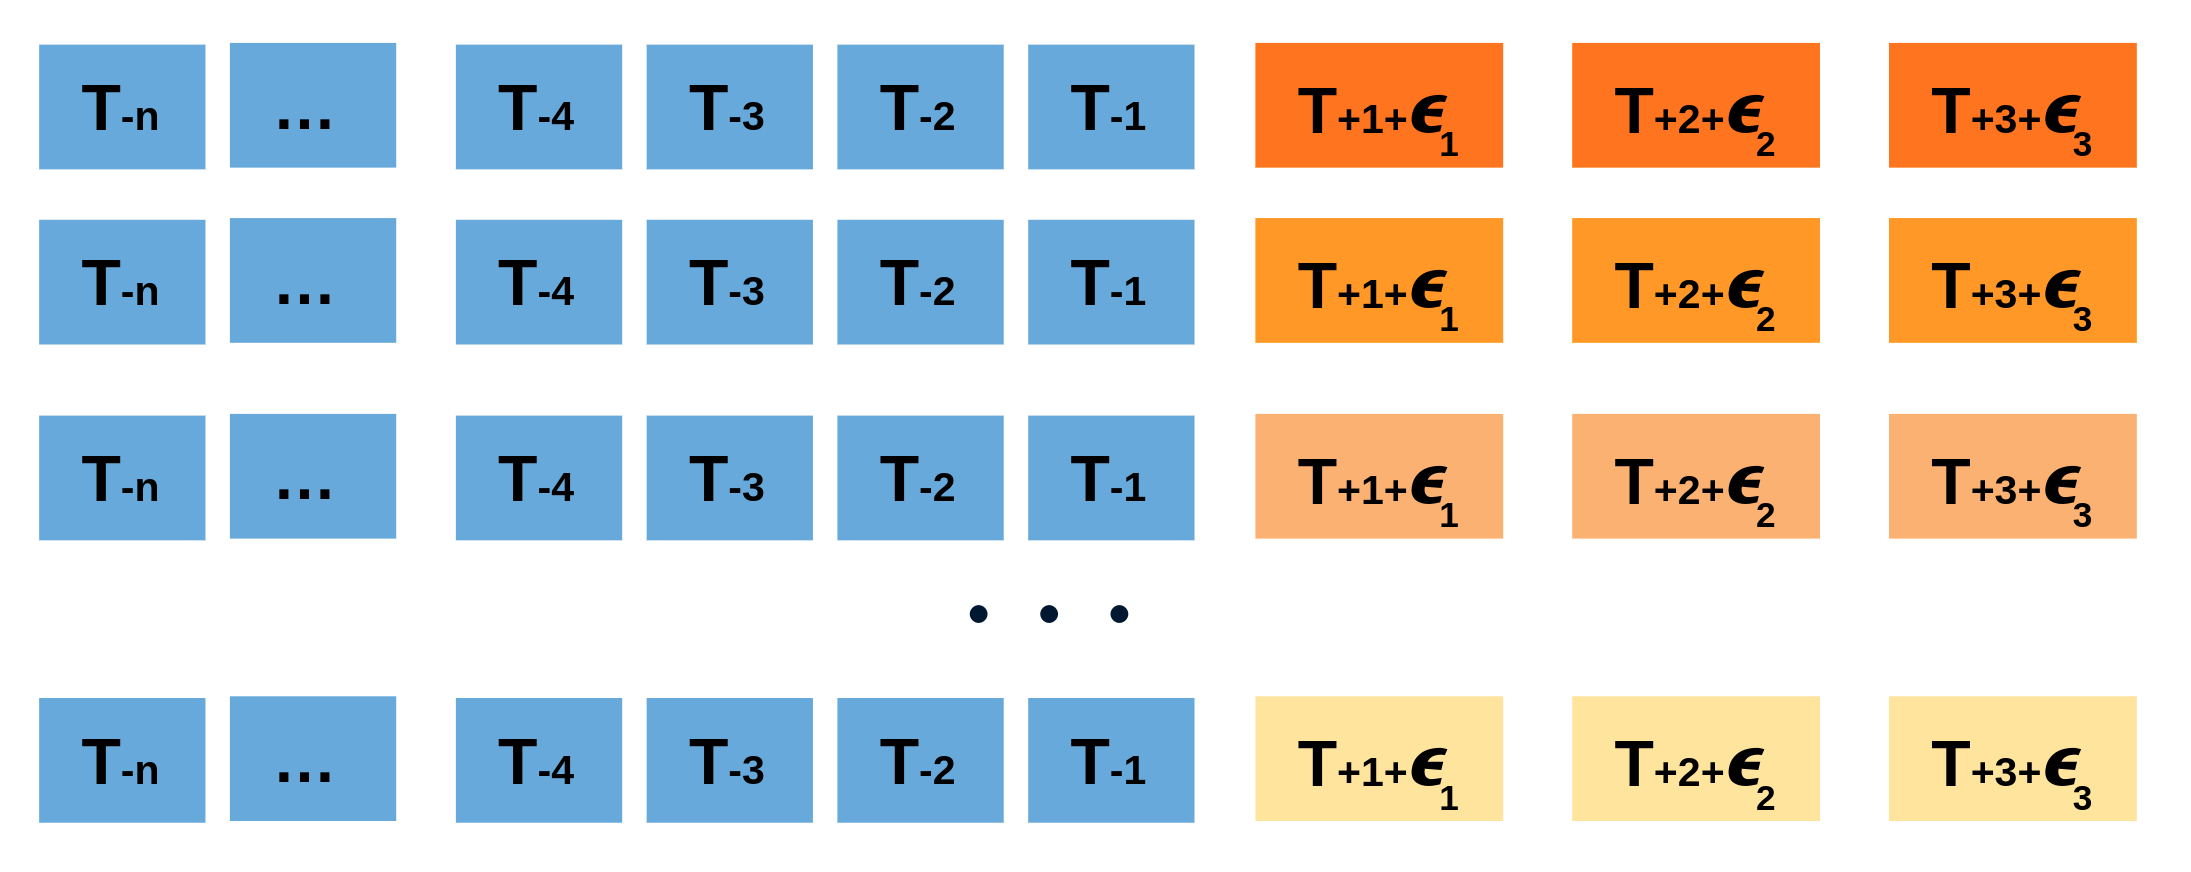
Bootstrapping predictions.
Using the outcome of the bootstrapping process, a prediction interval with a nominal coverage of $1 - \alpha$ (for example, $\alpha = 0.2$ for an 80% interval) is obtained by calculating the $\alpha/2$ and $1 - \alpha/2$ quantiles of the bootstrapped predictions at each forecasting horizon.
Animation of probabilistic bootstrapping prediction process.
Alternatively, it is also possible to fit a parametric distribution for each forecast horizon.
One of the main advantages of this strategy is that it requires only a single model to estimate any interval. However, performing hundreds or thousands of bootstrapping iterations can be computationally expensive and may not always be feasible.
Libraries and data
# Data processing
# ==============================================================================
import numpy as np
import pandas as pd
from skforecast.datasets import fetch_dataset
# Plots
# ==============================================================================
import matplotlib.pyplot as plt
import plotly.graph_objects as go
import plotly.io as pio
import plotly.offline as poff
from skforecast.plot import plot_residuals
pio.templates.default = 'seaborn'
pio.renderers.default = 'notebook'
poff.init_notebook_mode(connected=True)
plt.style.use('seaborn-v0_8-darkgrid')
# Modelling and Forecasting
# ==============================================================================
import skforecast
from lightgbm import LGBMRegressor
from skforecast.recursive import ForecasterRecursive
from skforecast.preprocessing import (
RollingFeatures,
CalendarFeatures,
ConformalIntervalCalibrator
)
from skforecast.model_selection import (
TimeSeriesFold,
backtesting_forecaster,
bayesian_search_forecaster
)
from skforecast.metrics import (
calculate_coverage,
winkler_score,
create_mean_pinball_loss
)
# Configuration
# ==============================================================================
import warnings
from pprint import pprint
warnings.filterwarnings('once')
color = '\033[1m\033[38;5;208m'
print(f'{color}Version skforecast: {skforecast.__version__}')
Version skforecast: 0.25.0
# Data download
# ==============================================================================
data = fetch_dataset(name='bike_sharing', raw=False)
data = data[['users', 'temp', 'hum', 'windspeed', 'holiday']]
data = data.loc['2011-04-01 00:00:00':'2012-10-20 23:00:00', :].copy()
data.head(3)
╭───────────────────────────────── bike_sharing ──────────────────────────────────╮ │ Description: │ │ Hourly usage of the bike share system in the city of Washington D.C. during the │ │ years 2011 and 2012. In addition to the number of users per hour, information │ │ about weather conditions and holidays is available. │ │ │ │ Source: │ │ Fanaee-T,Hadi. (2013). Bike Sharing Dataset. UCI Machine Learning Repository. │ │ https://doi.org/10.24432/C5W894. │ │ │ │ URL: │ │ https://raw.githubusercontent.com/skforecast/skforecast- │ │ datasets/main/data/bike_sharing_dataset_clean.csv │ │ │ │ Shape: 17544 rows x 11 columns │ ╰─────────────────────────────────────────────────────────────────────────────────╯
| users | temp | hum | windspeed | holiday | |
|---|---|---|---|---|---|
| date_time | |||||
| 2011-04-01 00:00:00 | 6.0 | 10.66 | 100.0 | 11.0014 | 0.0 |
| 2011-04-01 01:00:00 | 4.0 | 10.66 | 100.0 | 11.0014 | 0.0 |
| 2011-04-01 02:00:00 | 7.0 | 10.66 | 93.0 | 12.9980 | 0.0 |
Additional features are created based on calendar information: month, week, day of the week and hour. These variables are cyclical (hour 23 is as close to hour 0 as hour 1 is), so they are encoded with sine and cosine transformations that preserve this continuity.
The CalendarFeatures transformer is passed to the forecaster through the calendar_features argument. In this way, the calendar features are generated automatically from the datetime index during both training and prediction, and only the remaining exogenous variables (weather and holidays) have to be provided. For more details, see the calendar features user guide.
# Calendar features (cyclical encoding)
# ==============================================================================
calendar_transformer = CalendarFeatures(
features = ['month', 'week', 'day_of_week', 'hour'],
encoding = 'cyclical'
)
exog_features = ['holiday', 'hum', 'temp', 'windspeed']
# Preview of the features that the forecaster creates internally
calendar_transformer.fit_transform(data[['users']]).head(3)
| users | month_sin | month_cos | week_sin | week_cos | day_of_week_sin | day_of_week_cos | hour_sin | hour_cos | |
|---|---|---|---|---|---|---|---|---|---|
| date_time | |||||||||
| 2011-04-01 00:00:00 | 6.0 | 0.866025 | -0.5 | 0.999561 | 0.029633 | -0.433884 | -0.900969 | 0.000000 | 1.000000 |
| 2011-04-01 01:00:00 | 4.0 | 0.866025 | -0.5 | 0.999561 | 0.029633 | -0.433884 | -0.900969 | 0.258819 | 0.965926 |
| 2011-04-01 02:00:00 | 7.0 | 0.866025 | -0.5 | 0.999561 | 0.029633 | -0.433884 | -0.900969 | 0.500000 | 0.866025 |
To facilitate the training of the models, the search for optimal hyperparameters and the evaluation of their predictive accuracy, the data are divided into three separate sets: training, validation and test.
# Split train-validation-test
# ==============================================================================
end_train = '2012-06-30 23:59:00'
end_validation = '2012-10-01 23:59:00'
data_train = data.loc[: end_train, :]
data_val = data.loc[end_train:end_validation, :]
data_test = data.loc[end_validation:, :]
print(
f'Dates train : {data_train.index.min()} --- {data_train.index.max()} '
f'(n={len(data_train)})'
)
print(
f'Dates validation : {data_val.index.min()} --- {data_val.index.max()} '
f'(n={len(data_val)})'
)
print(
f'Dates test : {data_test.index.min()} --- {data_test.index.max()} '
f'(n={len(data_test)})'
)
Dates train : 2011-04-01 00:00:00 --- 2012-06-30 23:00:00 (n=10968) Dates validation : 2012-07-01 00:00:00 --- 2012-10-01 23:00:00 (n=2232) Dates test : 2012-10-02 00:00:00 --- 2012-10-20 23:00:00 (n=456)
# Plot partitions
# ==============================================================================
fig = go.Figure()
fig.add_trace(
go.Scatter(x=data_train.index, y=data_train['users'], mode='lines', name='Train')
)
fig.add_trace(
go.Scatter(x=data_val.index, y=data_val['users'], mode='lines', name='Validation')
)
fig.add_trace(
go.Scatter(x=data_test.index, y=data_test['users'], mode='lines', name='Test')
)
fig.update_layout(
title='Number of users',
xaxis_title='Time',
yaxis_title='Users',
width=800,
height=400,
margin=dict(l=20, r=20, t=35, b=20),
legend=dict(orientation='h', yanchor='top', y=1, xanchor='left', x=0.001)
)
fig.show()
Intervals with In-sample residuals
Intervals can be computed using in-sample residuals (residuals from the training set), either by calling the predict_interval() method, or by performing a full backtesting procedure. However, this can result in intervals that are too narrow (overly optimistic): since the residuals are computed on the same data used to fit the model, they tend to underestimate the error expected on new data.
✏️ Note
Hyperparameters used in this example have been previously optimized using a Bayesian search process. For more information about this process, please refer to Hyperparameter tuning and lags selection.
A ForecasterRecursive is created using a LightGBM regressor. As predictors, it uses the number of users in the previous 3 hours (lags 1, 2 and 3), the values around the same hour of the previous day (lags 23, 24 and 25) and of the previous week (lags 167, 168 and 169), the mean of the last 72 hours (RollingFeatures), the calendar features and the exogenous variables.
The forecaster is trained with the training and validation data. With store_in_sample_residuals = True, the residuals of the training process are stored in the forecaster.
# Create and fit forecaster
# ==============================================================================
params = {
'max_depth': 7,
'n_estimators': 300,
'learning_rate': 0.06,
'verbose': -1,
'random_state': 15926
}
lags = [1, 2, 3, 23, 24, 25, 167, 168, 169]
window_features = RollingFeatures(stats=['mean'], window_sizes=24 * 3)
forecaster = ForecasterRecursive(
estimator = LGBMRegressor(**params),
lags = lags,
window_features = window_features,
calendar_features = calendar_transformer
)
forecaster.fit(
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
store_in_sample_residuals = True
)
# In-sample residuals stored during fit
# ==============================================================================
print('Number of residuals stored:', len(forecaster.in_sample_residuals_))
forecaster.in_sample_residuals_
Number of residuals stored: 10000
array([ 38.2102196 , -4.28475005, -29.33611358, ..., -4.04491958,
-38.87536687, -6.27403615], shape=(10000,))
To limit memory usage, the forecaster stores a maximum of 10,000 residuals. If the training set is larger, as in this case, a random sample of the residuals is kept.
The backtesting_forecaster() function is used to estimate the prediction intervals for the entire test set. The following arguments are required to use this function:
use_in_sample_residuals: IfTrue, the in-sample residuals are used to compute the prediction intervals. Since these residuals are obtained from the training set, they are always available, but usually lead to overly optimistic intervals. IfFalse, the out-sample residuals are used to calculate the prediction intervals. These residuals are obtained from the validation set and are only available if theset_out_sample_residuals()method has been called. It is recommended to use out-sample residuals to achieve the desired coverage.interval: The quantiles used to calculate the prediction intervals. For example, if the 10th and 90th percentiles are used, the resulting prediction intervals will have a nominal coverage of 80%.interval_method: The method used to calculate the prediction intervals. Available options arebootstrappingandconformal.use_binned_residuals: IfTrue, the residuals are selected according to the range of the predicted value (binned residuals). This option is explained in a later section; for now, it is set toFalse.n_boot: The number of bootstrap samples to be used in estimating the prediction intervals wheninterval_method='bootstrapping'. The larger the number of samples, the more accurate the prediction intervals will be, but the longer the calculation will take.
# Backtesting with prediction intervals in test data using in-sample residuals
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = [0.1, 0.9], # 80% interval
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = True, # In-sample residuals
use_binned_residuals = False
)
predictions.head(5)
| fold | pred | lower_bound | upper_bound | |
|---|---|---|---|---|
| 2012-10-02 00:00:00 | 0 | 59.806858 | 33.935867 | 80.158493 |
| 2012-10-02 01:00:00 | 0 | 18.736429 | -6.017183 | 54.656118 |
| 2012-10-02 02:00:00 | 0 | 8.343854 | -17.411844 | 38.504087 |
| 2012-10-02 03:00:00 | 0 | 5.829008 | -18.563124 | 39.106756 |
| 2012-10-02 04:00:00 | 0 | 9.904088 | -12.436715 | 55.249514 |
# Functions to plot and evaluate predicted intervals
# ==============================================================================
def plot_predicted_intervals(
predictions: pd.DataFrame,
y_true: pd.DataFrame,
target_variable: str,
initial_x_zoom: list | None = None,
title: str | None = None,
xaxis_title: str | None = None,
yaxis_title: str | None = None,
):
"""
Plot predicted intervals vs real values. The point prediction is also
plotted if `predictions` contains the column 'pred'.
Parameters
----------
predictions : pandas DataFrame
Predicted intervals (columns 'lower_bound' and 'upper_bound') and,
optionally, point predictions (column 'pred').
y_true : pandas DataFrame
Real values of target variable.
target_variable : str
Name of target variable.
initial_x_zoom : list, default None
Initial zoom of x-axis.
title : str, default None
Title of the plot.
xaxis_title : str, default None
Title of x-axis.
yaxis_title : str, default None
Title of y-axis.
"""
fig = go.Figure()
if 'pred' in predictions.columns:
fig.add_trace(
go.Scatter(
name='Prediction', x=predictions.index, y=predictions['pred'],
mode='lines'
)
)
fig.add_trace(
go.Scatter(
name='Real value', x=y_true.index, y=y_true[target_variable], mode='lines'
)
)
fig.add_trace(
go.Scatter(
name='Upper Bound', x=predictions.index, y=predictions['upper_bound'],
mode='lines', marker=dict(color='#444'), line=dict(width=0),
showlegend=False
)
)
fig.add_trace(
go.Scatter(
name='Lower Bound', x=predictions.index, y=predictions['lower_bound'],
mode='lines', marker=dict(color='#444'), line=dict(width=0),
fillcolor='rgba(68, 68, 68, 0.3)', fill='tonexty', showlegend=False
)
)
fig.update_layout(
title=title, xaxis_title=xaxis_title, yaxis_title=yaxis_title, width=800,
height=400, margin=dict(l=20, r=20, t=35, b=20), hovermode='x',
xaxis=dict(range=initial_x_zoom),
legend=dict(orientation='h', yanchor='top', y=1.1, xanchor='left', x=0.001)
)
fig.show()
def evaluate_predicted_intervals(
predictions: pd.DataFrame,
y_true: pd.Series,
nominal_coverage: float = 0.8,
verbose: bool = True,
) -> dict:
"""
Calculate the empirical coverage, the area and the Winkler score of the
predicted intervals.
Parameters
----------
predictions : pandas DataFrame
Predicted intervals (columns 'lower_bound' and 'upper_bound').
y_true : pandas Series
Real values of target variable.
nominal_coverage : float, default 0.8
Nominal coverage of the intervals. Used to calculate the Winkler score.
verbose : bool, default True
Print the results.
Returns
-------
results : dict
Coverage, area and Winkler score of the intervals.
"""
coverage = calculate_coverage(
y_true = y_true,
lower_bound = predictions['lower_bound'],
upper_bound = predictions['upper_bound']
)
area = (predictions['upper_bound'] - predictions['lower_bound']).sum()
winkler = winkler_score(
y_true = y_true,
lower_bound = predictions['lower_bound'],
upper_bound = predictions['upper_bound'],
alpha = 1 - nominal_coverage
)
if verbose:
print(f'Predicted interval coverage: {round(100 * coverage, 2)} %')
print(f'Area of the interval: {round(area, 2)}')
print(f'Winkler score: {round(winkler, 2)}')
return {'coverage': coverage, 'area': area, 'winkler_score': winkler}
def conditional_coverage(
predictions: pd.DataFrame,
y_true: pd.Series,
n_groups: int = 3,
) -> pd.DataFrame:
"""
Calculate the empirical coverage and the mean width of the predicted
intervals conditioned on the predicted value. Predictions are divided into
`n_groups` groups of equal size according to the quantiles of 'pred'.
Parameters
----------
predictions : pandas DataFrame
Point predictions (column 'pred') and predicted intervals (columns
'lower_bound' and 'upper_bound').
y_true : pandas Series
Real values of target variable.
n_groups : int, default 3
Number of groups.
Returns
-------
results : pandas DataFrame
Coverage (%) and mean width of the intervals for each group.
"""
inside = y_true.between(predictions['lower_bound'], predictions['upper_bound'])
width = predictions['upper_bound'] - predictions['lower_bound']
groups = pd.qcut(predictions['pred'], q=n_groups, precision=0)
results = pd.DataFrame({
'coverage (%)': 100 * inside.groupby(groups, observed=True).mean(),
'mean width': width.groupby(groups, observed=True).mean()
})
results.index.name = 'Predicted users'
return results
# Plot intervals
# ==============================================================================
plot_predicted_intervals(
predictions = predictions,
y_true = data_test,
target_variable = 'users',
xaxis_title = 'Date time',
yaxis_title = 'users',
)
# Coverage, area and Winkler score of the intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 60.75 % Area of the interval: 42972.89 Winkler score: 309.76
The prediction intervals exhibit overconfidence: they tend to be excessively narrow, resulting in an empirical coverage (around 61%) far below the nominal coverage (80%). This happens because in-sample residuals tend to overestimate the predictive capacity of the model.
# Store results for later comparison
# ==============================================================================
predictions_in_sample_residuals = predictions.copy()
Out-sample residuals (non-conditioned on predicted values)
To address the issue of overly optimistic intervals, it is possible to use out-sample residuals (residuals from a validation set not seen during training) to estimate the prediction intervals. These residuals can be obtained through backtesting.
# Backtesting on validation data to obtain out-sample residuals
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_train]))
_, predictions_val = backtesting_forecaster(
forecaster = forecaster,
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
cv = cv,
metric = 'mean_absolute_error',
)
# Out-sample residuals distribution
# ==============================================================================
residuals = data.loc[predictions_val.index, 'users'] - predictions_val['pred']
print(pd.Series(np.where(residuals < 0, 'negative', 'positive')).value_counts())
plt.rcParams.update({'font.size': 8})
_ = plot_residuals(residuals=residuals, figsize=(7, 4))
positive 1281 negative 951 Name: count, dtype: int64

The out-sample residuals are not centred at zero: there are more positive than negative residuals, which means that the model tends to underestimate the number of users in the validation period. Since the bootstrapping process adds these residuals to the predictions, this bias is transferred to the intervals, which are shifted upwards.
With the set_out_sample_residuals() method, the out-sample residuals are stored in the forecaster object so that they can be used to estimate the prediction intervals.
# Store out-sample residuals in the forecaster
# ==============================================================================
forecaster.set_out_sample_residuals(
y_true = data.loc[predictions_val.index, 'users'],
y_pred = predictions_val['pred']
)
Now that the new residuals have been added to the forecaster, the prediction intervals can be calculated using use_in_sample_residuals = False.
# Backtesting with prediction intervals in test data using out-sample residuals
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = [0.1, 0.9], # 80% interval
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = False, # Out-sample residuals
use_binned_residuals = False
)
predictions.head(3)
| fold | pred | lower_bound | upper_bound | |
|---|---|---|---|---|
| 2012-10-02 00:00:00 | 0 | 59.806858 | 31.578561 | 131.861512 |
| 2012-10-02 01:00:00 | 0 | 18.736429 | -7.495726 | 136.241295 |
| 2012-10-02 02:00:00 | 0 | 8.343854 | -23.354319 | 140.180018 |
# Plot intervals
# ==============================================================================
plot_predicted_intervals(
predictions = predictions,
y_true = data_test,
target_variable = 'users',
xaxis_title = 'Date time',
yaxis_title = 'users',
)
# Coverage, area and Winkler score of the intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 83.11 % Area of the interval: 100660.88 Winkler score: 311.36
The prediction intervals derived from the out-sample residuals are considerably wider than those based on the in-sample residuals, and the empirical coverage (83.1%) is now close to the nominal coverage (80%). However, the Winkler score barely changes (from 310 to 311): what is gained in coverage is lost in sharpness.
Looking at the plot, the intervals have a similar width regardless of the predicted value, because all the residuals are sampled from a single pool. As a result, the intervals are excessively wide when the number of users is low (night hours), and they may be too narrow around the peaks of demand. The next section shows how to make the width of the interval depend on the predicted value.
# Store results for later comparison
# ==============================================================================
predictions_out_sample_residuals = predictions.copy()
Intervals conditioned on predicted values (binned residuals)
The bootstrapping process assumes that the residuals are independently distributed so that they can be used independently of the predicted value. In reality, this is rarely true; in most cases, the magnitude of the residuals is correlated with the magnitude of the predicted value. For instance, one would hardly expect the error to be the same when the predicted number of users is close to zero as when it is in the hundreds.
To account for the dependence between the residuals and the predicted values, skforecast allows partitioning the residuals into K bins, where each bin is associated with a range of predicted values. Using this strategy, the bootstrapping process samples the residuals from different bins depending on the predicted value, which can improve the coverage of the interval while adjusting the width if necessary, allowing the model to better distribute the uncertainty of its predictions.
Internally, skforecast uses a QuantileBinner class to bin data into quantile-based bins using numpy.percentile. This class is similar to KBinsDiscretizer but faster for binning data into quantile-based bins. Bin intervals are defined following the convention: bins[i-1] <= x < bins[i]. The binning process can be adjusted using the argument binner_kwargs of the Forecaster object.
The number of bins is a hyperparameter. A higher number of bins allows the intervals to adapt better to the predicted value, but fewer residuals are available in each bin, so the estimation of the quantiles becomes noisier. In this example, 15 bins are used. If the number of bins is tuned, it must be done using validation data, never the test set.
# Create and train forecaster
# ==============================================================================
forecaster = ForecasterRecursive(
estimator = LGBMRegressor(**params),
lags = lags,
window_features = window_features,
calendar_features = calendar_transformer,
binner_kwargs = {'n_bins': 15}
)
forecaster.fit(
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
store_in_sample_residuals = True
)
During the training process, the forecaster uses the in-sample predictions to define intervals (bins). Residuals are then assigned to these bins based on their corresponding predicted values (binner_intervals_ attribute). For example, if the bin "0" has an interval of (-2.06, 7.34), it means that it will store the residuals of the predictions that fall within that interval.
When the prediction intervals are calculated, the residuals are sampled from the bin corresponding to the predicted value. This way, the model can adjust the width of the intervals depending on the predicted value, which can help to better distribute the uncertainty of the predictions.
# Intervals associated with the bins
# ==============================================================================
pprint(forecaster.binner_intervals_)
{0: (-2.058499067584011, 7.339683335728002),
1: (7.339683335728002, 15.786737846689995),
2: (15.786737846689995, 30.53493920944861),
3: (30.53493920944861, 59.12817141401169),
4: (59.12817141401169, 90.53042339424537),
5: (90.53042339424537, 120.3837770378804),
6: (120.3837770378804, 151.12755002609902),
7: (151.12755002609902, 178.99957394146344),
8: (178.99957394146344, 209.83991808145416),
9: (209.83991808145416, 247.60669961894214),
10: (247.60669961894214, 289.299070321893),
11: (289.299070321893, 338.21124164842377),
12: (338.21124164842377, 415.7439121230614),
13: (415.7439121230614, 524.3743996547786),
14: (524.3743996547786, 963.2802014321065)}
The set_out_sample_residuals() method will bin the residuals according to the intervals learned during fitting. To avoid using too much memory, the number of residuals stored per bin is limited to 10_000 // n_bins (666 residuals per bin in this example).
# Store out-sample residuals in the forecaster
# ==============================================================================
forecaster.set_out_sample_residuals(
y_true = data.loc[predictions_val.index, 'users'],
y_pred = predictions_val['pred']
)
# Number of out-sample residuals by bin
# ==============================================================================
for k, v in forecaster.out_sample_residuals_by_bin_.items():
print(f'Bin {k}: n={len(v)}')
Bin 0: n=62 Bin 1: n=154 Bin 2: n=97 Bin 3: n=153 Bin 4: n=91 Bin 5: n=73 Bin 6: n=95 Bin 7: n=111 Bin 8: n=88 Bin 9: n=163 Bin 10: n=185 Bin 11: n=203 Bin 12: n=199 Bin 13: n=241 Bin 14: n=317
The number of out-sample residuals is very different from one bin to another. The bins are defined with the quantiles of the in-sample predictions, so they contain the same number of in-sample residuals, but the predictions of the validation period are not evenly distributed among them. The least populated bin contains 62 residuals, which is enough to estimate the 10th and 90th percentiles, but it illustrates the practical limit when increasing the number of bins: the more bins, the fewer residuals are available to estimate the quantiles of each one.
# Distribution of the residuals by bin
# ==============================================================================
out_sample_residuals_by_bin_df = pd.DataFrame(
{k: pd.Series(v) for k, v in forecaster.out_sample_residuals_by_bin_.items()}
)
fig, ax = plt.subplots(figsize=(8, 3))
out_sample_residuals_by_bin_df.boxplot(ax=ax)
ax.set_title('Distribution of residuals by bin', fontsize=12)
ax.set_xlabel('Bin', fontsize=10)
ax.set_ylabel('Residuals', fontsize=10)
plt.show()

The box plots show how the spread and magnitude of the residuals differ depending on the predicted value. The residuals are higher and more dispersed when the predicted value is higher (higher bin), which is consistent with the intuition that errors tend to be larger when the predicted value is larger.
# Summary information of bins
# ==============================================================================
bins_summary = out_sample_residuals_by_bin_df.describe().T
bins_summary.index.name = 'bin'
bins_summary.insert(0, 'interval', bins_summary.index.map(forecaster.binner_intervals_))
bins_summary['interval'] = bins_summary['interval'].apply(lambda x: np.round(x, 2))
bins_summary
| interval | count | mean | std | min | 25% | 50% | 75% | max | |
|---|---|---|---|---|---|---|---|---|---|
| bin | |||||||||
| 0 | [-2.06, 7.34] | 62.0 | 1.323739 | 3.347242 | -4.344465 | -1.259973 | 0.967387 | 3.325592 | 10.696952 |
| 1 | [7.34, 15.79] | 154.0 | 0.279240 | 6.640277 | -8.765945 | -3.513490 | -0.987068 | 1.924822 | 46.118619 |
| 2 | [15.79, 30.53] | 97.0 | -0.265793 | 12.317799 | -20.991691 | -8.091929 | -2.404640 | 5.062957 | 71.615914 |
| 3 | [30.53, 59.13] | 153.0 | -3.551069 | 17.861359 | -44.938411 | -12.858413 | -5.399200 | 2.021401 | 144.221783 |
| 4 | [59.13, 90.53] | 91.0 | 2.468340 | 27.065248 | -41.798786 | -15.472666 | -4.347441 | 16.084610 | 102.192538 |
| 5 | [90.53, 120.38] | 73.0 | 10.643658 | 47.842949 | -56.812480 | -13.474935 | 4.883647 | 25.821022 | 339.788475 |
| 6 | [120.38, 151.13] | 95.0 | 8.612300 | 40.845478 | -105.853842 | -8.842125 | 8.037872 | 33.710405 | 235.907866 |
| 7 | [151.13, 179.0] | 111.0 | 12.843652 | 48.112488 | -124.015632 | -9.952662 | 16.766075 | 36.337500 | 271.643575 |
| 8 | [179.0, 209.84] | 88.0 | 17.021465 | 57.339997 | -159.379665 | -4.485558 | 18.808255 | 40.227259 | 283.611050 |
| 9 | [209.84, 247.61] | 163.0 | 19.304036 | 67.718674 | -168.493072 | -11.233863 | 11.541506 | 43.710252 | 314.792725 |
| 10 | [247.61, 289.3] | 185.0 | 10.899667 | 67.327189 | -181.286112 | -24.204218 | 12.128164 | 32.933237 | 450.494045 |
| 11 | [289.3, 338.21] | 203.0 | 10.028103 | 67.811943 | -270.643416 | -21.363678 | 6.964164 | 39.553606 | 278.429138 |
| 12 | [338.21, 415.74] | 199.0 | 16.813693 | 95.781002 | -313.442874 | -43.780630 | 15.126953 | 69.469935 | 317.206594 |
| 13 | [415.74, 524.37] | 241.0 | 8.692868 | 93.367482 | -404.054991 | -25.404532 | 18.603071 | 58.290293 | 245.170100 |
| 14 | [524.37, 963.28] | 317.0 | 20.988463 | 120.387893 | -471.337222 | -14.876610 | 40.520290 | 96.287346 | 370.026279 |
Finally, the prediction intervals are estimated again, this time using out-sample residuals conditioned on the predicted values.
# Backtesting with prediction intervals in test data using out-sample binned
# residuals
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = [0.1, 0.9], # 80% interval
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = False, # Out-sample residuals
use_binned_residuals = True # Binned residuals
)
predictions.head(3)
| fold | pred | lower_bound | upper_bound | |
|---|---|---|---|---|
| 2012-10-02 00:00:00 | 0 | 59.806858 | 29.467702 | 89.647428 |
| 2012-10-02 01:00:00 | 0 | 18.736429 | 6.098207 | 43.457271 |
| 2012-10-02 02:00:00 | 0 | 8.343854 | 4.542673 | 18.806828 |
# Plot intervals
# ==============================================================================
plot_predicted_intervals(
predictions = predictions,
y_true = data_test,
target_variable = 'users',
xaxis_title = 'Date time',
yaxis_title = 'users',
)
# Coverage, area and Winkler score of the intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 86.4 % Area of the interval: 96776.35 Winkler score: 266.75
When using out-sample residuals conditioned on the predicted value, the uncertainty is distributed differently: the intervals are narrow when the predicted number of users is low and wide when it is high. Compared with the non-binned out-sample residuals, the area is reduced by around 4% (from 100,661 to 96,776) and the Winkler score improves from 311 to 267. The empirical coverage (86.4%) is above the nominal coverage (80%), which means that the estimated intervals are conservative.
One possible reason for this conservative behavior is that the out-sample residuals are obtained with a model trained only with the training partition, and they show a positive bias in the validation period. The final model, trained with the training and validation data, is expected to have smaller errors, so these residuals slightly overstate its uncertainty.
# Store results for later comparison
# ==============================================================================
predictions_out_sample_residuals_binned = predictions.copy()
The following plot compares the prediction intervals obtained using in-sample residuals, out-sample residuals, and out-sample residuals conditioned on the predicted values.
# Plot intervals using: in-sample residuals, out-sample residuals and binned residuals
# ==============================================================================
fig, ax = plt.subplots(figsize=(8, 4))
ax.fill_between(
predictions_out_sample_residuals.index,
predictions_out_sample_residuals['lower_bound'],
predictions_out_sample_residuals['upper_bound'],
color='gray',
alpha=0.9,
label='Out-sample residuals',
zorder=1
)
ax.fill_between(
predictions_out_sample_residuals_binned.index,
predictions_out_sample_residuals_binned['lower_bound'],
predictions_out_sample_residuals_binned['upper_bound'],
color='#fc4f30',
alpha=0.7,
label='Out-sample binned residuals',
zorder=2
)
ax.fill_between(
predictions_in_sample_residuals.index,
predictions_in_sample_residuals['lower_bound'],
predictions_in_sample_residuals['upper_bound'],
color='#30a2da',
alpha=0.9,
label='In-sample residuals',
zorder=3
)
ax.set_xlim(pd.to_datetime(['2012-10-08 00:00:00', '2012-10-15 00:00:00']))
ax.set_title('Prediction intervals with different residuals', fontsize=12)
ax.legend();

The global coverage does not tell the whole story. A good interval should achieve the nominal coverage not only on average, but also for the different levels of demand. To verify it, the test predictions are divided into three groups of equal size according to the predicted number of users (low, medium and high), and the empirical coverage and the mean width of the intervals are calculated for each group.
# Coverage and width of the intervals conditioned on the predicted value
# ==============================================================================
methods = {
'In-sample residuals': predictions_in_sample_residuals,
'Out-sample residuals': predictions_out_sample_residuals,
'Out-sample binned residuals': predictions_out_sample_residuals_binned
}
conditional_results = pd.concat(
{
name: conditional_coverage(pred, data_test['users'])
for name, pred in methods.items()
},
axis=1
)
conditional_results.round(1)
| In-sample residuals | Out-sample residuals | Out-sample binned residuals | ||||
|---|---|---|---|---|---|---|
| coverage (%) | mean width | coverage (%) | mean width | coverage (%) | mean width | |
| Predicted users | ||||||
| (3.0, 143.0] | 88.8 | 73.1 | 89.5 | 207.9 | 83.6 | 71.1 |
| (143.0, 332.0] | 56.6 | 96.2 | 92.1 | 227.3 | 88.8 | 224.2 |
| (332.0, 897.0] | 36.8 | 113.4 | 67.8 | 227.0 | 86.8 | 341.4 |
The table makes the progression between the three approaches explicit:
In-sample residuals: the coverage collapses as the predicted value increases, from 88.8% in the group of low predictions to 36.8% in the group of high predictions. The intervals are too narrow precisely where the errors of the model are larger.
Out-sample residuals: the global coverage of 83.1% is the average of two opposite errors. The intervals have a mean width of more than 200 users in all the groups, which is excessive for the low predictions and insufficient for the high ones, where the coverage only reaches 67.8%.
Out-sample binned residuals: the coverage is similar in the three groups (83.6%, 88.8% and 86.8%) and the width of the intervals grows with the predicted value, from 71 to 341 users.
Therefore, using out-sample residuals corrects the global calibration of the intervals, and conditioning them on the predicted value corrects where the uncertainty is placed.
⚠️ Warning
Probabilistic forecasting in production
The correct estimation of prediction intervals depends on the residuals being representative of future errors. For this reason, out-sample residuals should be used. However, the dynamics of the series and models can change over time, so it is important to monitor and regularly update the residuals. It can be done easily using the set_out_sample_residuals() method.
Prediction of multiple intervals
The backtesting_forecaster function not only allows estimating a single prediction interval but also estimating multiple quantiles (percentiles) from which multiple prediction intervals can be constructed. This is useful to evaluate the quality of the prediction intervals for a range of probabilities. Furthermore, it has almost no additional computational cost compared to estimating a single interval.
Next, several percentiles are predicted and, from these, prediction intervals are created for different nominal coverage levels (10%, 20%, 30%, 40%, 50%, 60%, 70%, 80%, 90% and 95%). Then, their empirical coverage is assessed.
# Prediction of multiple quantiles
# ==============================================================================
quantiles = [
0.025, 0.05, 0.10, 0.15, 0.20, 0.25, 0.30, 0.35, 0.40, 0.45, 0.50, 0.55, 0.60,
0.65, 0.70, 0.75, 0.80, 0.85, 0.90, 0.95, 0.975
]
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = quantiles,
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = False, # Out-sample residuals
use_binned_residuals = True # Binned residuals
)
predictions.head()
| fold | pred | q_0.025 | q_0.05 | q_0.1 | q_0.15 | q_0.2 | q_0.25 | q_0.3 | q_0.35 | ... | q_0.55 | q_0.6 | q_0.65 | q_0.7 | q_0.75 | q_0.8 | q_0.85 | q_0.9 | q_0.95 | q_0.975 | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 2012-10-02 00:00:00 | 0 | 59.806858 | 21.394854 | 24.753867 | 29.467702 | 37.208407 | 40.160613 | 44.006751 | 46.109929 | 50.144769 | ... | 61.676650 | 69.842802 | 71.116587 | 73.430910 | 76.556363 | 78.404018 | 83.305776 | 89.647428 | 101.135168 | 119.594460 |
| 2012-10-02 01:00:00 | 0 | 18.736429 | 3.823246 | 4.428840 | 6.098207 | 7.258918 | 7.725225 | 10.062596 | 11.331109 | 12.543273 | ... | 19.587360 | 21.750654 | 22.426858 | 25.942015 | 30.120835 | 34.927024 | 38.594785 | 43.457271 | 61.588106 | 98.180927 |
| 2012-10-02 02:00:00 | 0 | 8.343854 | 2.589883 | 3.199794 | 4.542673 | 5.256008 | 5.728307 | 6.035306 | 7.036289 | 7.580606 | ... | 9.537155 | 10.481016 | 11.073380 | 12.040345 | 12.825298 | 14.228836 | 16.807480 | 18.806828 | 26.983981 | 47.329914 |
| 2012-10-02 03:00:00 | 0 | 5.829008 | 2.284566 | 2.598515 | 3.469681 | 3.758989 | 4.273794 | 4.617065 | 5.109465 | 5.570610 | ... | 7.352128 | 7.582263 | 8.050841 | 8.665297 | 9.176679 | 9.753946 | 11.335291 | 12.562592 | 15.071611 | 17.257213 |
| 2012-10-02 04:00:00 | 0 | 9.904088 | 3.389574 | 4.603494 | 5.203550 | 6.004520 | 7.163223 | 7.718639 | 8.018983 | 8.336490 | ... | 10.356019 | 10.974005 | 11.592354 | 12.082498 | 13.292125 | 14.722783 | 15.853279 | 17.719854 | 18.651374 | 26.036931 |
5 rows × 23 columns
# Calculate coverage and area for each interval
# ==============================================================================
intervals = [
[0.025, 0.975], [0.05, 0.95], [0.10, 0.90], [0.15, 0.85], [0.20, 0.80],
[0.25, 0.75], [0.30, 0.70], [0.35, 0.65], [0.40, 0.60], [0.45, 0.55]
]
nominal_coverages = [100 * (upper_q - lower_q) for lower_q, upper_q in intervals]
observed_coverages = []
observed_areas = []
for lower_q, upper_q in intervals:
lower_bound = predictions[f'q_{lower_q}']
upper_bound = predictions[f'q_{upper_q}']
observed_coverage = calculate_coverage(
y_true = data_test['users'],
lower_bound = lower_bound,
upper_bound = upper_bound
)
observed_coverages.append(100 * observed_coverage)
observed_areas.append((upper_bound - lower_bound).sum())
results = pd.DataFrame({
'Interval': intervals,
'Nominal coverage (%)': nominal_coverages,
'Observed coverage (%)': observed_coverages,
'Area': observed_areas
})
results.round(2)
| Interval | Nominal coverage (%) | Observed coverage (%) | Area | |
|---|---|---|---|---|
| 0 | [0.025, 0.975] | 95.0 | 96.27 | 160756.57 |
| 1 | [0.05, 0.95] | 90.0 | 93.64 | 131115.55 |
| 2 | [0.1, 0.9] | 80.0 | 86.40 | 96776.35 |
| 3 | [0.15, 0.85] | 70.0 | 80.48 | 75580.06 |
| 4 | [0.2, 0.8] | 60.0 | 69.96 | 59399.98 |
| 5 | [0.25, 0.75] | 50.0 | 59.87 | 46079.68 |
| 6 | [0.3, 0.7] | 40.0 | 47.59 | 34936.25 |
| 7 | [0.35, 0.65] | 30.0 | 36.18 | 25362.27 |
| 8 | [0.4, 0.6] | 20.0 | 23.90 | 16575.47 |
| 9 | [0.45, 0.55] | 10.0 | 12.28 | 8215.91 |
For all the nominal levels, the observed coverage is higher than the nominal coverage (for example, 86.4% for the 80% interval and 59.9% for the 50% interval). This confirms that the intervals estimated with out-sample binned residuals are conservative across the whole distribution, not only for a particular interval. As expected, the area grows with the nominal coverage: wider intervals are the price of capturing a higher proportion of the observations.
Predict bootstrap, interval, quantile and distribution
The previous sections have demonstrated the use of the backtesting process to estimate the prediction interval over a given period of time. The goal is to mimic the behavior of the model in production by running predictions at regular intervals, incrementally updating the input data.
Alternatively, it is possible to run a single prediction that forecasts N steps ahead without going through the entire backtesting process. In such cases, skforecast provides four different methods: predict_bootstrapping, predict_interval, predict_quantiles and predict_dist. For detailed information on how to use these methods, please refer to the documentation.
Conformal Prediction
Conformal prediction is a framework for constructing prediction intervals that are guaranteed to contain the true value with a specified probability (coverage probability), under the assumption that the data are exchangeable. In time series this assumption holds only approximately, so the empirical coverage should always be validated. It works by combining the predictions of a point-forecasting model with its past residuals (differences between previous predictions and actual values). These residuals help estimate the uncertainty in the forecast and determine the width of the prediction interval that is then added to the point forecast. Skforecast implements Split Conformal Prediction (SCP).
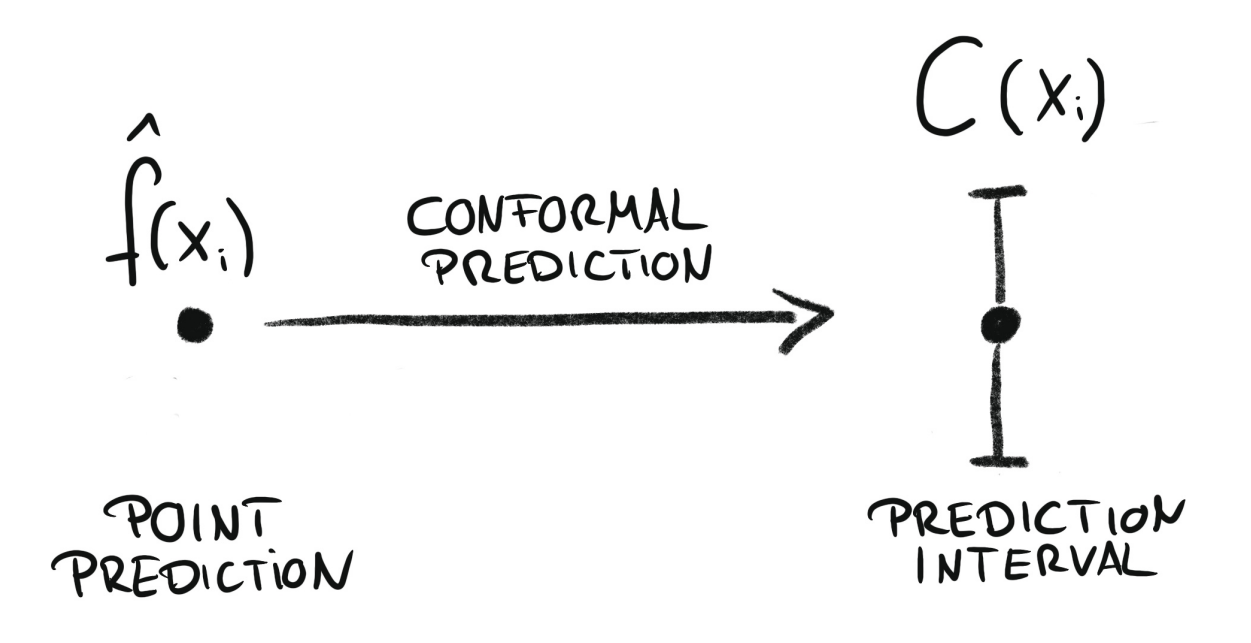
Conformal regression turns point predictions into prediction intervals. Source: Introduction To Conformal Prediction With Python: A Short Guide For Quantifying Uncertainty Of Machine Learning Models
by Christoph Molnar. https://leanpub.com/conformal-prediction
Animation of probabilistic conformal prediction process.
Conformal methods can also calibrate prediction intervals generated by other techniques, such as quantile regression or bootstrapped residuals. In this case, the conformal method adjusts the prediction intervals to ensure that they remain valid with respect to the coverage probability. Skforecast provides this functionality through the ConformalIntervalCalibrator transformer, as shown in the last section of this document.
⚠️ Warning
There are several well-established methods for conformal prediction, each with its own characteristics and assumptions. However, when applied to time series forecasting, their coverage guarantees are only valid for one-step-ahead predictions. For multi-step-ahead predictions, the coverage probability is not guaranteed, so it is advisable to validate the empirical coverage with backtesting. Skforecast implements Split Conformal Prediction (SCP) due to its balance between complexity and performance. More details can be found in the conformal prediction user guide.
A backtesting process is applied to estimate the prediction intervals for the test set, this time using the conformal method. Since the out-sample residuals are already stored in the forecaster object, the use_in_sample_residuals argument is set to False, and use_binned_residuals is set to True to allow adaptive intervals. With use_binned_residuals = False, the same correction is applied to all the predictions, so the conformal intervals have a constant width. With binned residuals, the width adapts to the predicted value.
# Backtesting with conformal prediction intervals in test data (out-sample
# binned residuals)
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = 0.8, # 80% interval
interval_method = 'conformal',
use_in_sample_residuals = False, # Out-sample residuals
use_binned_residuals = True # Adaptive conformal
)
predictions_conformal = predictions.copy()
predictions.head(3)
| fold | pred | lower_bound | upper_bound | |
|---|---|---|---|---|
| 2012-10-02 00:00:00 | 0 | 59.806858 | 29.467702 | 90.146014 |
| 2012-10-02 01:00:00 | 0 | 18.736429 | 5.466255 | 32.006603 |
| 2012-10-02 02:00:00 | 0 | 8.343854 | 2.784521 | 13.903186 |
# Plot intervals
# ==============================================================================
plot_predicted_intervals(
predictions = predictions,
y_true = data_test,
target_variable = 'users',
xaxis_title = 'Date time',
yaxis_title = 'users',
)
# Coverage, area and Winkler score of the intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 76.75 % Area of the interval: 61826.74 Winkler score: 257.98
The resulting intervals show an empirical coverage (76.8%) slightly lower than the nominal 80%, but close to it. In addition, their area (around 61,800) is more than a third smaller than that of the bootstrapped intervals with out-sample binned residuals (around 96,800), and they achieve a lower Winkler score (258 vs 267).
Quantile Regression
Quantile regression is a technique for estimating the conditional quantiles of a response variable. By combining the predictions of two quantile regressors, an interval can be constructed, where each model estimates one of the bounds of the interval. For example, models trained for $Q = 0.1$ and $Q = 0.9$ produce an 80% prediction interval ($90\% - 10\% = 80\%$).
If a machine learning algorithm capable of modeling quantiles is used as the estimator in a forecaster, the predict method will return predictions for a specified quantile. By creating two forecasters, each configured with a different quantile, their predictions can be combined to generate a prediction interval.
As opposed to least squares regression, which is intended to estimate the conditional mean of the response variable given certain values of the predictor variables, quantile regression aims at estimating the conditional quantiles of the response variable. For a continuous distribution function, the $\alpha$-quantile $Q_{\alpha}(x)$ is defined such that the probability of $Y$ being smaller than $Q_{\alpha}(x)$ is, for a given $X=x$, equal to $\alpha$. For example, 36% of the population values are lower than the quantile $Q=0.36$. The best-known quantile is the 50%-quantile, more commonly called the median.
Several machine learning algorithms are capable of modeling quantiles. Some of them are:
Just as the squared-error loss function is used to train models that predict the mean value, a specific loss function is needed in order to train models that predict quantiles. The most common metric used for quantile regression is called quantile loss or pinball loss:
$$\text{pinball}(y, \hat{y}) = \frac{1}{n_{\text{samples}}} \sum_{i=0}^{n_{\text{samples}}-1} \alpha \max(y_i - \hat{y}_i, 0) + (1 - \alpha) \max(\hat{y}_i - y_i, 0)$$where $\alpha$ is the target quantile, $y$ the real value and $\hat{y}$ the quantile prediction. Note that here $\alpha$ denotes the target quantile (as in the alpha argument of LightGBM and create_mean_pinball_loss), not the miscoverage level used in the Winkler score.
It can be seen that the loss differs depending on the evaluated quantile. The higher the quantile, the more the loss function penalizes underestimates, and the less it penalizes overestimates. As with MSE and MAE, the goal is to minimize its values (the lower the loss, the better).
Two disadvantages of quantile regression, compared to the bootstrap approach to prediction intervals, are that each quantile requires its own estimator and quantile regression is not available for all types of regression models.
⚠️ Warning
Limitations of quantile regression in recursive multi-step forecasting
- Quantile crossing: the two models are trained independently, so nothing prevents the predicted lower bound from being above the predicted upper bound at some steps.
-
Recursive predictions: in a recursive forecaster, each prediction is used as a lag to predict the next step. A model trained for the quantile 0.1 feeds its own low predictions back as inputs, so, beyond the first step, its output is no longer a true quantile of the multi-step distribution. Direct strategies (
ForecasterDirect) do not have this limitation, since predictions are never used as predictors.
For these reasons, the empirical coverage should always be validated. More details can be found in the quantile regression user guide and in Probabilistic forecasting: prediction intervals for multi-step time series forecasting.
# Create forecasters: one for each limit of the interval
# ==============================================================================
# The forecasters obtained for alpha=0.1 and alpha=0.9 produce an 80% prediction
# interval (90% - 10% = 80%).
# Forecaster for quantile 10%
forecaster_q10 = ForecasterRecursive(
estimator = LGBMRegressor(
objective = 'quantile',
metric = 'quantile',
alpha = 0.1,
random_state = 15926,
verbose = -1
),
lags = lags,
window_features = window_features,
calendar_features = calendar_transformer
)
# Forecaster for quantile 90%
forecaster_q90 = ForecasterRecursive(
estimator = LGBMRegressor(
objective = 'quantile',
metric = 'quantile',
alpha = 0.9,
random_state = 15926,
verbose = -1
),
lags = lags,
window_features = window_features,
calendar_features = calendar_transformer
)
Next, a Bayesian search is performed with bayesian_search_forecaster to find the best hyperparameters for the quantile regressors. When validating a quantile regression model, it is important to use a metric that is coherent with the quantile being evaluated. In this case, the pinball loss is used. Skforecast provides the function create_mean_pinball_loss to calculate the pinball loss for a given quantile.
Since return_best = True by default, once the search is finished, each forecaster is refitted with the best configuration found.
# Bayesian search of hyperparameters for each quantile forecaster
# ==============================================================================
def search_space(trial):
return {
'n_estimators' : trial.suggest_int('n_estimators', 100, 500, step=50),
'max_depth' : trial.suggest_int('max_depth', 3, 10, step=1),
'learning_rate' : trial.suggest_float('learning_rate', 0.01, 0.1)
}
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_train]))
results_q10, _ = bayesian_search_forecaster(
forecaster = forecaster_q10,
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
cv = cv,
metric = create_mean_pinball_loss(alpha=0.1),
search_space = search_space,
n_trials = 10
)
results_q90, _ = bayesian_search_forecaster(
forecaster = forecaster_q90,
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
cv = cv,
metric = create_mean_pinball_loss(alpha=0.9),
search_space = search_space,
n_trials = 10
)
print('Best results for quantile 0.1')
display(results_q10.head(3))
print('Best results for quantile 0.9')
display(results_q90.head(3))
Best results for quantile 0.1
| trial_number | lags | params | mean_pinball_loss_q | n_estimators | max_depth | learning_rate | |
|---|---|---|---|---|---|---|---|
| 0 | 7 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 450, 'max_depth': 8, 'learnin... | 12.204477 | 450.0 | 8.0 | 0.064992 |
| 1 | 2 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 500, 'max_depth': 8, 'learnin... | 12.406089 | 500.0 | 8.0 | 0.053284 |
| 2 | 6 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 300, 'max_depth': 7, 'learnin... | 12.617053 | 300.0 | 7.0 | 0.067096 |
Best results for quantile 0.9
| trial_number | lags | params | mean_pinball_loss_q | n_estimators | max_depth | learning_rate | |
|---|---|---|---|---|---|---|---|
| 0 | 1 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 300, 'max_depth': 8, 'learnin... | 13.808398 | 300.0 | 8.0 | 0.048080 |
| 1 | 3 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 250, 'max_depth': 5, 'learnin... | 13.961826 | 250.0 | 5.0 | 0.075614 |
| 2 | 7 | [1, 2, 3, 23, 24, 25, 167, 168, 169] | {'n_estimators': 450, 'max_depth': 8, 'learnin... | 14.026557 | 450.0 | 8.0 | 0.064992 |
Once the best hyperparameters have been found for each forecaster, a backtesting process is applied again using the test data.
# Backtesting on test data
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric_q10, predictions_q10 = backtesting_forecaster(
forecaster = forecaster_q10,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = create_mean_pinball_loss(alpha=0.1)
)
metric_q90, predictions_q90 = backtesting_forecaster(
forecaster = forecaster_q90,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = create_mean_pinball_loss(alpha=0.9)
)
predictions = pd.DataFrame({
'lower_bound': predictions_q10['pred'],
'upper_bound': predictions_q90['pred']
})
predictions_quantile = predictions.copy()
predictions.head(3)
| lower_bound | upper_bound | |
|---|---|---|
| 2012-10-02 00:00:00 | 36.489269 | 67.089314 |
| 2012-10-02 01:00:00 | 8.904616 | 39.421416 |
| 2012-10-02 02:00:00 | 4.849228 | 25.912180 |
# Plot intervals
# ==============================================================================
plot_predicted_intervals(
predictions = predictions,
y_true = data_test,
target_variable = 'users',
title = 'Real value vs predicted intervals in test data',
xaxis_title = 'Date time',
yaxis_title = 'users',
)
# Coverage, area and Winkler score of the intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 75.88 % Area of the interval: 78362.23 Winkler score: 274.59
The intervals estimated with quantile regression achieve an empirical coverage of 75.9%, slightly below the nominal 80%. Both their area (around 78,400) and their Winkler score (275) lie between those of conformal prediction and those of bootstrapping with out-sample binned residuals.
Results comparison
To select the most appropriate method for a given use case, both the empirical coverage (how well the intervals capture the true value relative to the nominal 80% target) and the width of the intervals (area) must be compared. Ideally, a good prediction interval is narrow while meeting, or slightly exceeding, the nominal coverage. The Winkler score summarizes both aspects in a single value (the lower the better).
The following table shows the three metrics for the five methods explored in this document.
# Comparison of probabilistic forecasting methods
# ==============================================================================
methods = {
'In-sample residuals': predictions_in_sample_residuals,
'Out-sample residuals': predictions_out_sample_residuals,
'Out-sample binned residuals': predictions_out_sample_residuals_binned,
'Conformal prediction': predictions_conformal,
'Quantile regression': predictions_quantile
}
comparison = pd.DataFrame({
name: evaluate_predicted_intervals(pred, data_test['users'], verbose=False)
for name, pred in methods.items()
}).T
comparison['coverage'] = 100 * comparison['coverage']
comparison.insert(0, 'nominal_coverage', 80.0)
comparison.columns = [
'Nominal coverage (%)', 'Empirical coverage (%)', 'Area', 'Winkler score'
]
comparison.round(2)
| Nominal coverage (%) | Empirical coverage (%) | Area | Winkler score | |
|---|---|---|---|---|
| In-sample residuals | 80.0 | 60.75 | 42972.89 | 309.76 |
| Out-sample residuals | 80.0 | 83.11 | 100660.88 | 311.36 |
| Out-sample binned residuals | 80.0 | 86.40 | 96776.35 | 266.75 |
| Conformal prediction | 80.0 | 76.75 | 61826.74 | 257.98 |
| Quantile regression | 80.0 | 75.88 | 78362.23 | 274.59 |
Several conclusions can be drawn from the results:
In-sample residuals produce the narrowest intervals, but their coverage (60.8%) is far below the nominal 80%. Many observations fall outside the intervals, which is heavily penalized by the Winkler score (310).
Out-sample residuals correct the global calibration (83.1%), but at the cost of intervals with a similar width for all the predictions: too wide when the number of users is low and too narrow in the peaks of demand. This is why the Winkler score does not improve (311) despite the good global coverage.
Out-sample binned residuals correct where the uncertainty is placed. The coverage is similar for all levels of demand, the area is slightly smaller and the Winkler score improves (267). The intervals are conservative (86.4%).
Conformal prediction with binned residuals achieves the best Winkler score (258): a coverage close to the nominal one (76.8%) with an area more than a third smaller than that of the bootstrapped intervals. In addition, it is the fastest method, since no bootstrapping is needed.
Quantile regression results in a coverage slightly below the nominal one (75.9%) with an intermediate area and Winkler score (275). It requires training one model per quantile and has the limitations described above for recursive multi-step forecasting.
These results correspond to a single time series and a test period of 19 days, so they should not be generalized: no method is the best in all cases. As a general recommendation, out-sample residuals should always be preferred to in-sample residuals, residuals conditioned on the predicted value (binned) help to place the uncertainty where it is needed, and the empirical coverage should always be validated with backtesting before using the intervals in production.
External calibration of prediction intervals
It is common that the prediction intervals obtained with the different methods do not achieve the desired coverage because they are under or overconfident. To address this issue, skforecast provides the ConformalIntervalCalibrator transformer, which can be used to calibrate the prediction intervals obtained with other methods.
The ConformalIntervalCalibrator uses the Split Conformal Prediction (SCP) method to learn the correction factor needed to expand or shrink the prediction intervals so that they are valid with respect to a given coverage probability. The process consists of the following steps:
Prediction intervals are estimated for a calibration set, a partition of the data not used to train the model.
Using the predicted intervals and the actual values of the calibration set, the transformer learns the correction factor needed to calibrate these intervals.
The prediction intervals of new data (in this example, the test set) are adjusted using the learned correction factor.
⚠️ Warning
It is important to ensure that the calibration set resembles the data on which the intervals will be calibrated (here, the test set). Otherwise, the learned correction factor will not apply well and the resulting calibration will be incorrect.
To illustrate the process, the prediction intervals of the test set are estimated using bootstrapping with in-sample residuals conditioned on the predicted value (binned). As shown before, in-sample residuals result in overconfident intervals.
# Backtesting with prediction intervals in test data using in-sample residuals
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_validation]))
metric, predictions = backtesting_forecaster(
forecaster = forecaster,
y = data['users'],
exog = data[exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = [0.1, 0.9], # 80% interval
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = True, # In-sample residuals
use_binned_residuals = True # Binned residuals
)
_ = evaluate_predicted_intervals(predictions=predictions, y_true=data_test['users'])
Predicted interval coverage: 63.6 % Area of the interval: 40614.62 Winkler score: 285.95
The same procedure is applied to the validation set, which is used as the calibration set. The forecaster is trained with the training data and the intervals of the validation set are predicted with backtesting.
# Predict intervals for the calibration set (validation)
# ==============================================================================
cv = TimeSeriesFold(steps = 24, initial_train_size = len(data.loc[:end_train]))
_, predictions_cal = backtesting_forecaster(
forecaster = forecaster,
y = data.loc[:end_validation, 'users'],
exog = data.loc[:end_validation, exog_features],
cv = cv,
metric = 'mean_absolute_error',
interval = [0.1, 0.9], # 80% interval
interval_method = 'bootstrapping',
n_boot = 150,
use_in_sample_residuals = True, # In-sample residuals
use_binned_residuals = True # Binned residuals
)
# Fit a ConformalIntervalCalibrator transformer using the calibration set
# ==============================================================================
calibrator = ConformalIntervalCalibrator(nominal_coverage=0.8)
calibrator.fit(
y_true = data.loc[predictions_cal.index, 'users'],
y_pred_interval = predictions_cal[['lower_bound', 'upper_bound']]
)
calibrator
ConformalIntervalCalibrator
General Information
- Nominal coverage: 0.8
- Coverage in fit data: {'users': 0.6258960573476703}
- Symmetric interval: True
- Symmetric correction factor: {'users': 24.75615813795512}
- Asymmetric correction factor lower: {'users': 3.177857309776222}
- Asymmetric correction factor upper: {'users': 39.10658583151591}
- Fitted series: ['users']
The ConformalIntervalCalibrator reports a coverage of 63% in the calibration set, well below the nominal 80%. Consequently, the learned correction factor is positive (24.76 users), indicating that the intervals are too narrow and that both bounds must be moved away from the prediction by that amount to achieve the desired coverage.
The already calculated prediction intervals of the test set are now calibrated.
# Calibrate prediction intervals of the test set
# ==============================================================================
predictions_calibrated = calibrator.transform(
predictions[['lower_bound', 'upper_bound']]
)
print('Prediction intervals before calibration')
print('---------------------------------------')
display(predictions[['lower_bound', 'upper_bound']].head(3))
print('Prediction intervals after calibration')
print('--------------------------------------')
predictions_calibrated[['lower_bound', 'upper_bound']].head(3)
Prediction intervals before calibration ---------------------------------------
| lower_bound | upper_bound | |
|---|---|---|
| 2012-10-02 00:00:00 | 38.444511 | 78.198434 |
| 2012-10-02 01:00:00 | 8.704568 | 31.928207 |
| 2012-10-02 02:00:00 | 2.792277 | 15.154949 |
Prediction intervals after calibration --------------------------------------
| lower_bound | upper_bound | |
|---|---|---|
| 2012-10-02 00:00:00 | 13.688353 | 102.954592 |
| 2012-10-02 01:00:00 | -16.051590 | 56.684365 |
| 2012-10-02 02:00:00 | -21.963881 | 39.911107 |
# Coverage, area and Winkler score of the calibrated intervals (on test data)
# ==============================================================================
_ = evaluate_predicted_intervals(
predictions = predictions_calibrated,
y_true = data_test['users']
)
Predicted interval coverage: 78.73 % Area of the interval: 63192.24 Winkler score: 267.7
After calibration, the empirical coverage of the intervals in the test set increases from 63.6% to 78.7%, very close to the nominal coverage of 80%, and the Winkler score improves from 286 to 268.
Since the correction factor is a constant value applied to all the intervals, the lower bound can take negative values when the predicted number of users is low. If the target variable cannot be negative, as in this case, the lower bound can be clipped to zero.
Session information
import session_info
session_info.show(html=False)
----- lightgbm 4.7.0 matplotlib 3.10.9 numpy 2.4.6 pandas 2.3.3 plotly 6.9.0 session_info v1.0.1 skforecast 0.25.0 ----- IPython 9.15.0 jupyter_client 8.9.1 jupyter_core 5.9.1 ----- Python 3.13.14 | packaged by conda-forge | (main, Jun 12 2026, 09:44:26) [MSC v.1944 64 bit (AMD64)] Windows-11-10.0.26200-SP0 ----- Session information updated at 2026-09-22 09:44
Citation
How to cite this document
If you use this document or any part of it, please acknowledge the source, thank you!
Probabilistic forecasting with machine learning by Joaquín Amat Rodrigo and Javier Escobar Ortiz, available under Attribution-NonCommercial-ShareAlike 4.0 International (CC BY-NC-SA 4.0 DEED) at https://cienciadedatos.net/documentos/py42-probabilistic-forecasting.html
How to cite skforecast
If you use skforecast for a publication, we would appreciate if you cite the published software.
Zenodo:
Amat Rodrigo, Joaquin, & Escobar Ortiz, Javier. (2026). skforecast (v0.25.0). Zenodo. https://doi.org/10.5281/zenodo.8382788
APA:
Amat Rodrigo, J., & Escobar Ortiz, J. (2026). skforecast (Version 0.25.0) [Computer software]. https://doi.org/10.5281/zenodo.8382788
BibTeX:
@software{skforecast, author = {Amat Rodrigo, Joaquin and Escobar Ortiz, Javier}, title = {skforecast}, version = {0.25.0}, month = {09}, year = {2026}, license = {BSD-3-Clause}, url = {https://skforecast.org/}, doi = {10.5281/zenodo.8382788} }
Did you like the article? Your support is important
Your contribution will help me to continue generating free educational content. Many thanks! 😊



This work by Joaquín Amat Rodrigo and Javier Escobar Ortiz is licensed under a Attribution-NonCommercial-ShareAlike 4.0 International.
Allowed:
-
Share: copy and redistribute the material in any medium or format.
-
Adapt: remix, transform, and build upon the material.
Under the following terms:
-
Attribution: You must give appropriate credit, provide a link to the license, and indicate if changes were made. You may do so in any reasonable manner, but not in any way that suggests the licensor endorses you or your use.
-
NonCommercial: You may not use the material for commercial purposes.
-
ShareAlike: If you remix, transform, or build upon the material, you must distribute your contributions under the same license as the original.